01What it is
Judix scores AI agents and RAG systems while they run, step by step, so you find out an agent is going wrong in the turn it is taking, not in next week's report.
02The problem
Logs tell you what happened. Offline evals tell you about last week. Neither tells you that the agent is going wrong right now, and by the time you read either one, a user has already had the bad answer.
03How it works
A deterministic engine written in Rust scores every agent step and every RAG claim with zero model calls, so each score costs $0. It makes two passes over every step; a model is only asked afterwards, to explain the why. There are two front doors to one engine: a CLI for local runs and a streaming HTTP endpoint for live systems.
04The proof
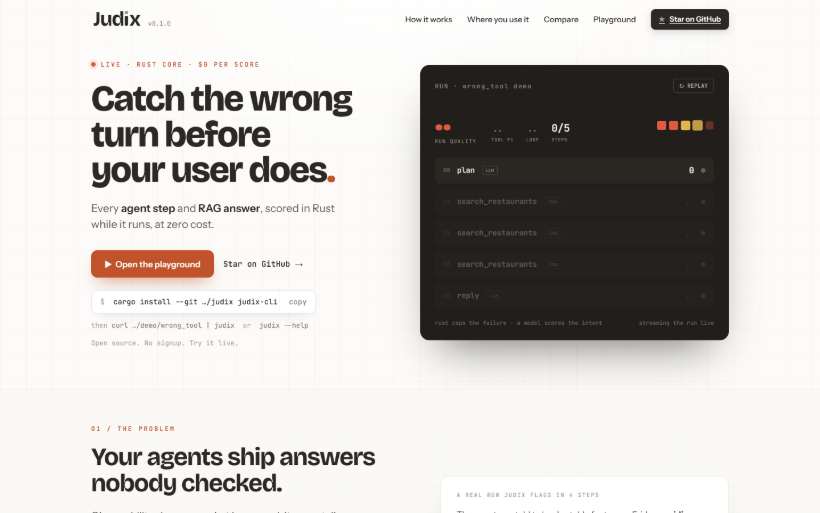
It ships with its own worst case on the page. An agent told to book a table for two on Friday, avoiding downtown, searched downtown three times, then announced it would try downtown again. Judix scored that run 15 out of 100, capped at 59 by a critical failure, and flagged it across four separate steps.
05Where it is now
Live and open source at v0.1.0, with a public playground and no signup.